New releaseOptimum-NVIDIA Unlocking blazingly fast LLM inference in just 1 line of codeHugging Face Blog · 1 min read
New releaseComparing the Performance of LLMs: A Deep Dive into Roberta, Llama 2, and Mistral for Disaster Tweets Analysis with LoraHugging Face Blog · 1 min read
New releaseIntroducing Prodigy-HF: a direct integration with Hugging FaceHugging Face Blog · 1 min read
New releaseInteractively explore your Huggingface dataset with one line of codeHugging Face Blog · 1 min read
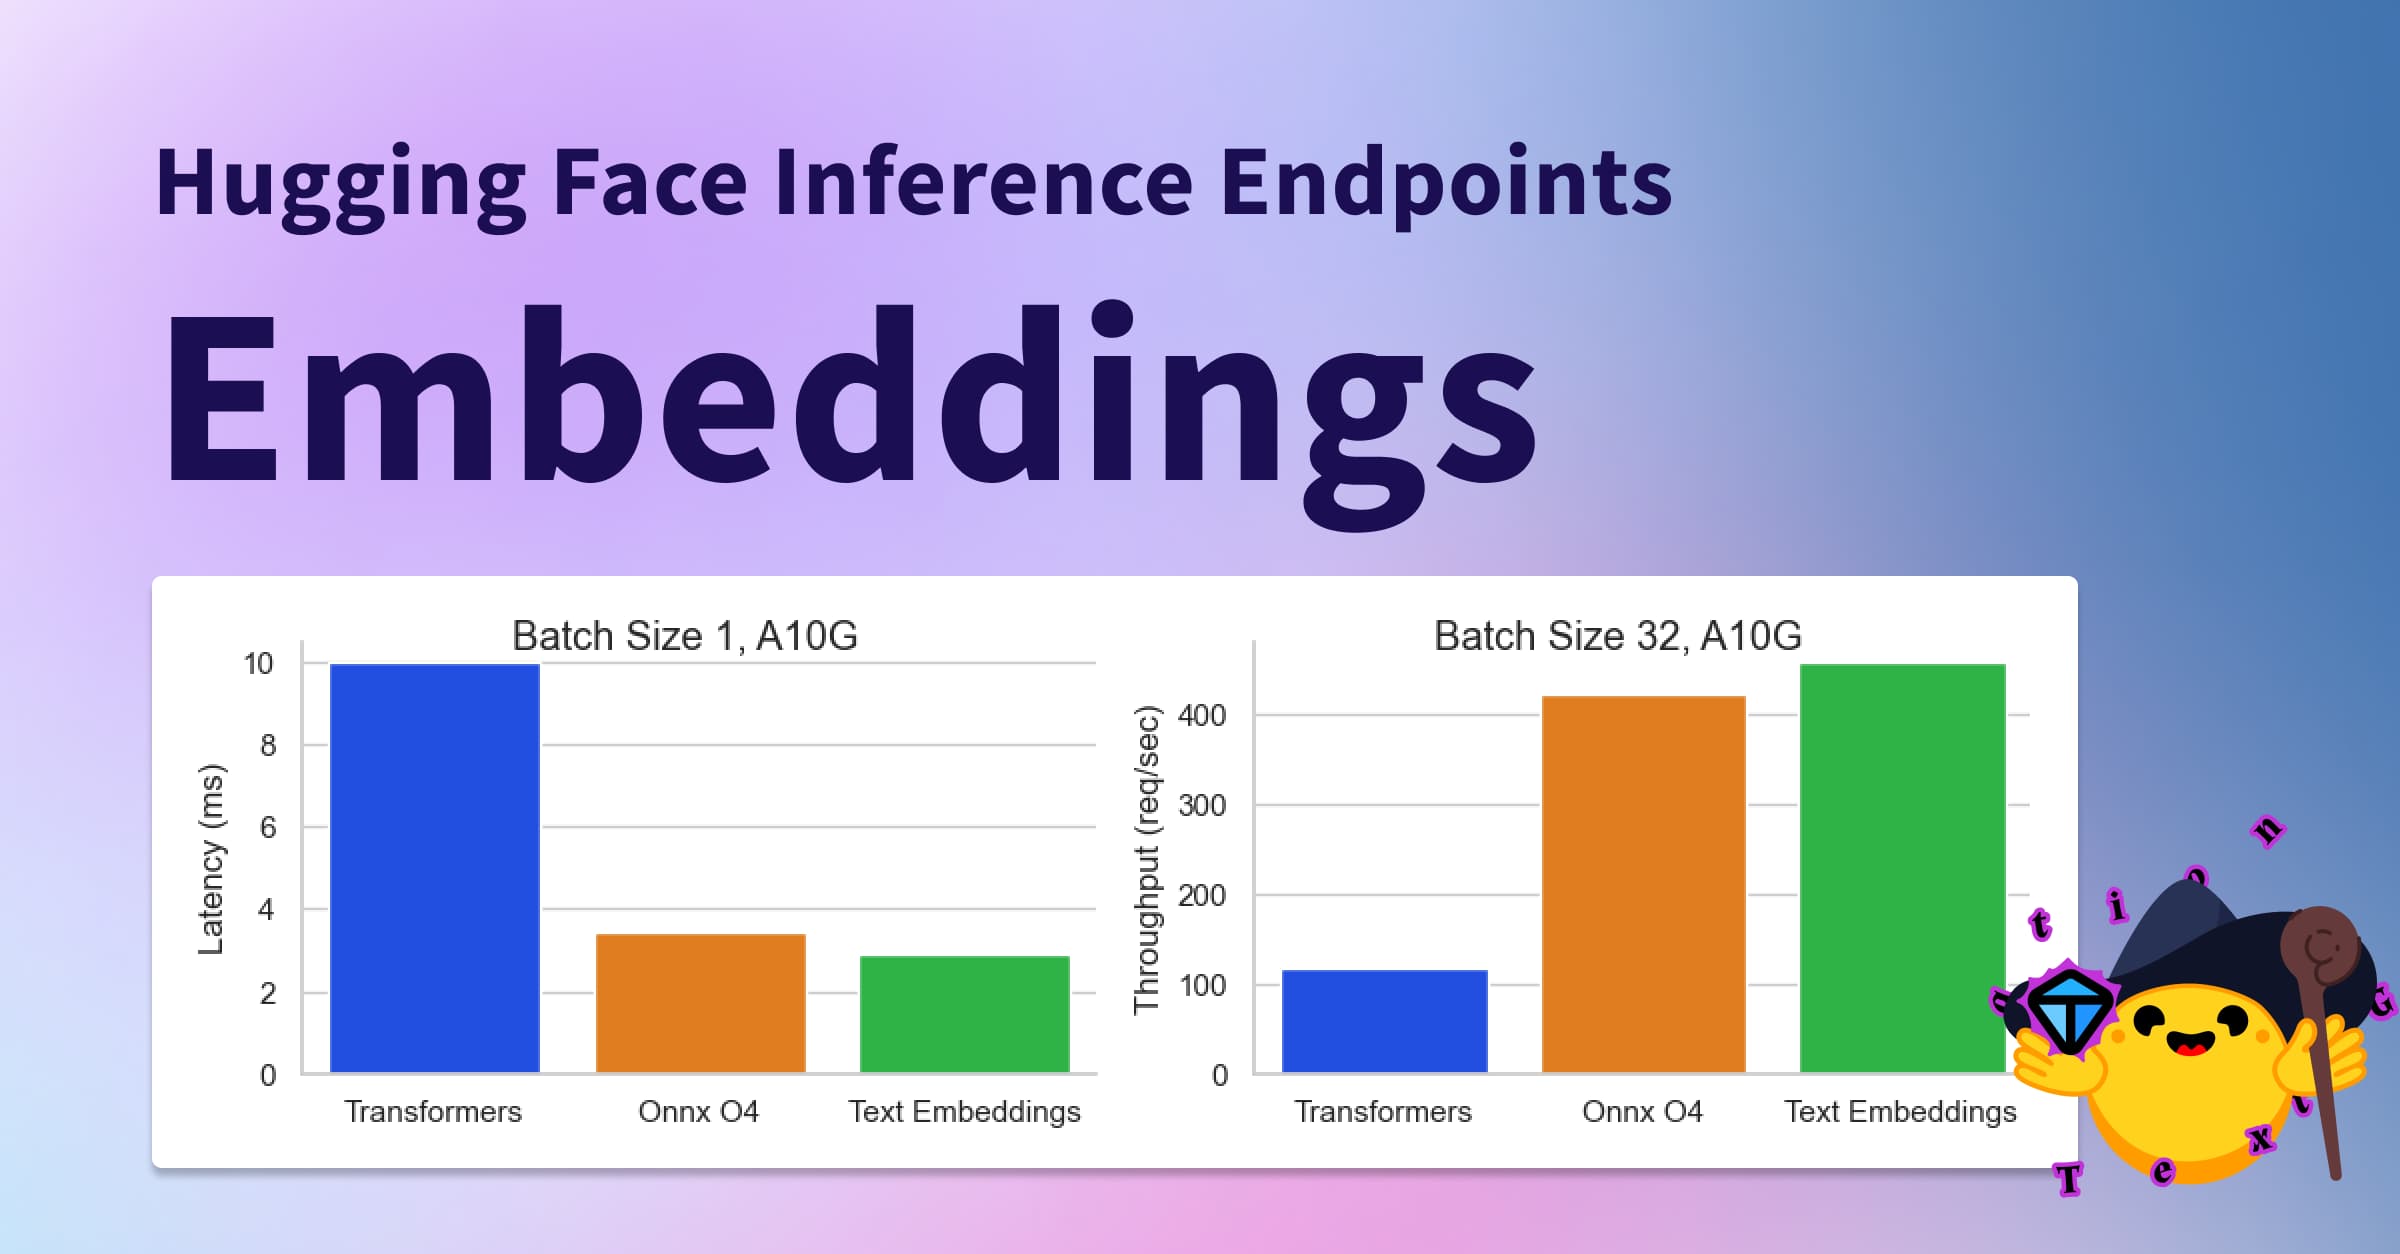
New releaseDeploy Embedding Models with Hugging Face Inference EndpointsHugging Face Blog · 1 min read
New releaseGradio-Lite: Serverless Gradio Running Entirely in Your BrowserHugging Face Blog · 1 min read