New releaseFine-Tune W2V2-Bert for low-resource ASR with 🤗 TransformersHugging Face Blog · 1 min read
New releasePreference Tuning LLMs with Direct Preference Optimization MethodsHugging Face Blog · 1 min read
New releaseAccelerating SD Turbo and SDXL Turbo Inference with ONNX Runtime and OliveHugging Face Blog · 1 min read
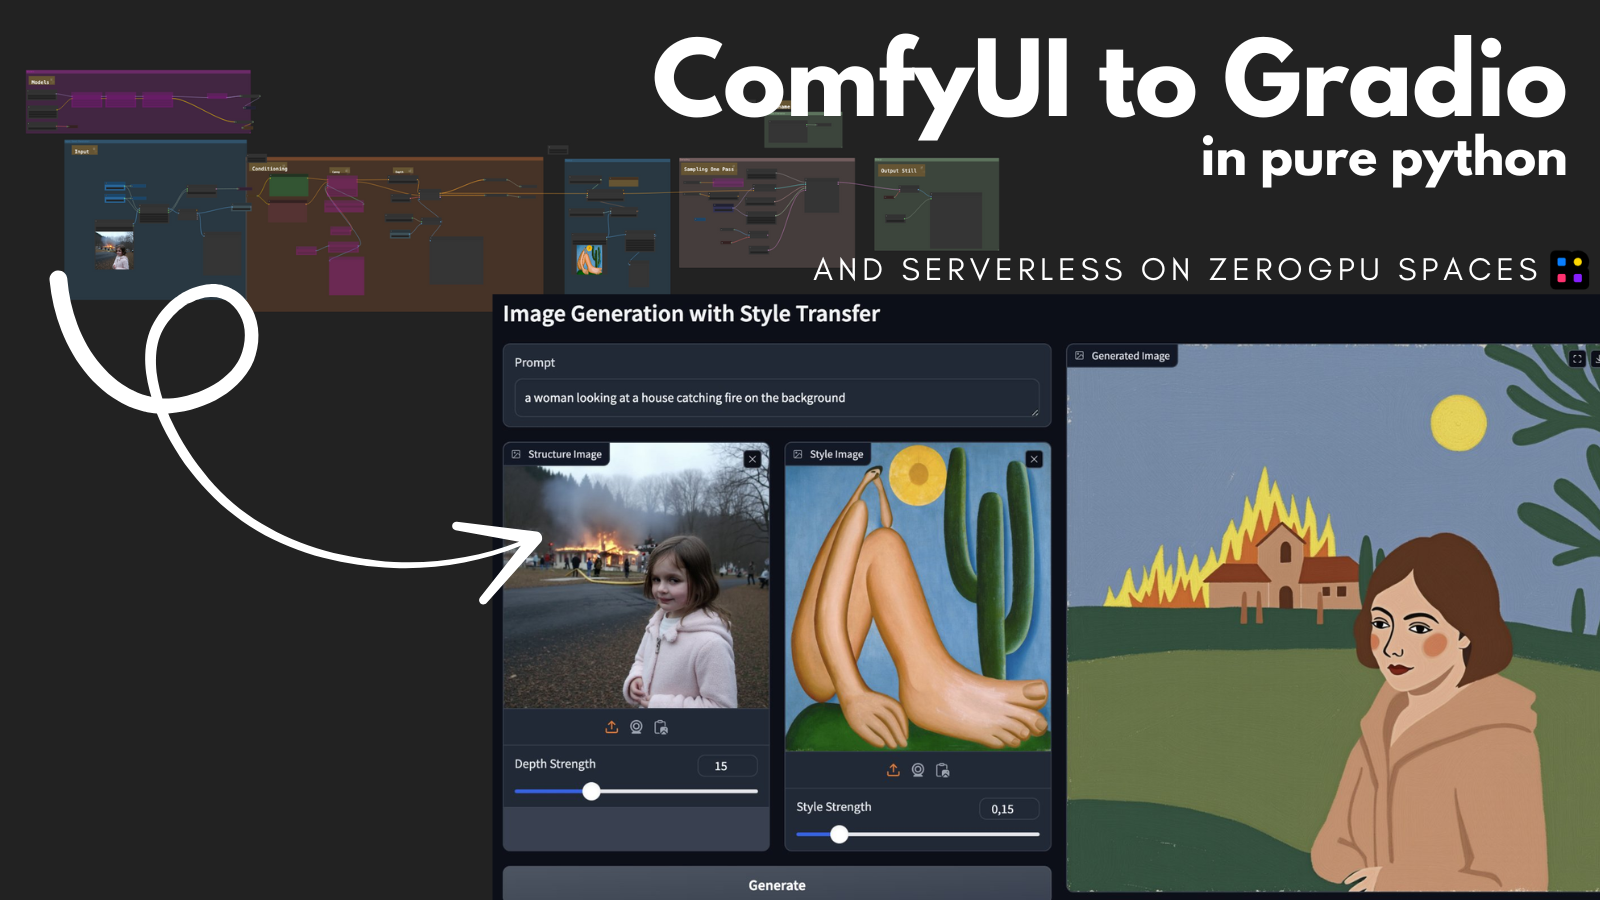
New releaseRun ComfyUI workflows for free with Gradio on Hugging Face SpacesHugging Face Blog · 1 min read
New releaseA guide to setting up your own Hugging Face leaderboard: an end-to-end example with Vectara's hallucination leaderboardHugging Face Blog · 1 min read
New releaseAMD + 🤗: Large Language Models Out-of-the-Box Acceleration with AMD GPUHugging Face Blog · 1 min read
New releaseIntroducing Prodigy-HF: a direct integration with Hugging FaceHugging Face Blog · 1 min read
New releaseInteractively explore your Huggingface dataset with one line of codeHugging Face Blog · 1 min read
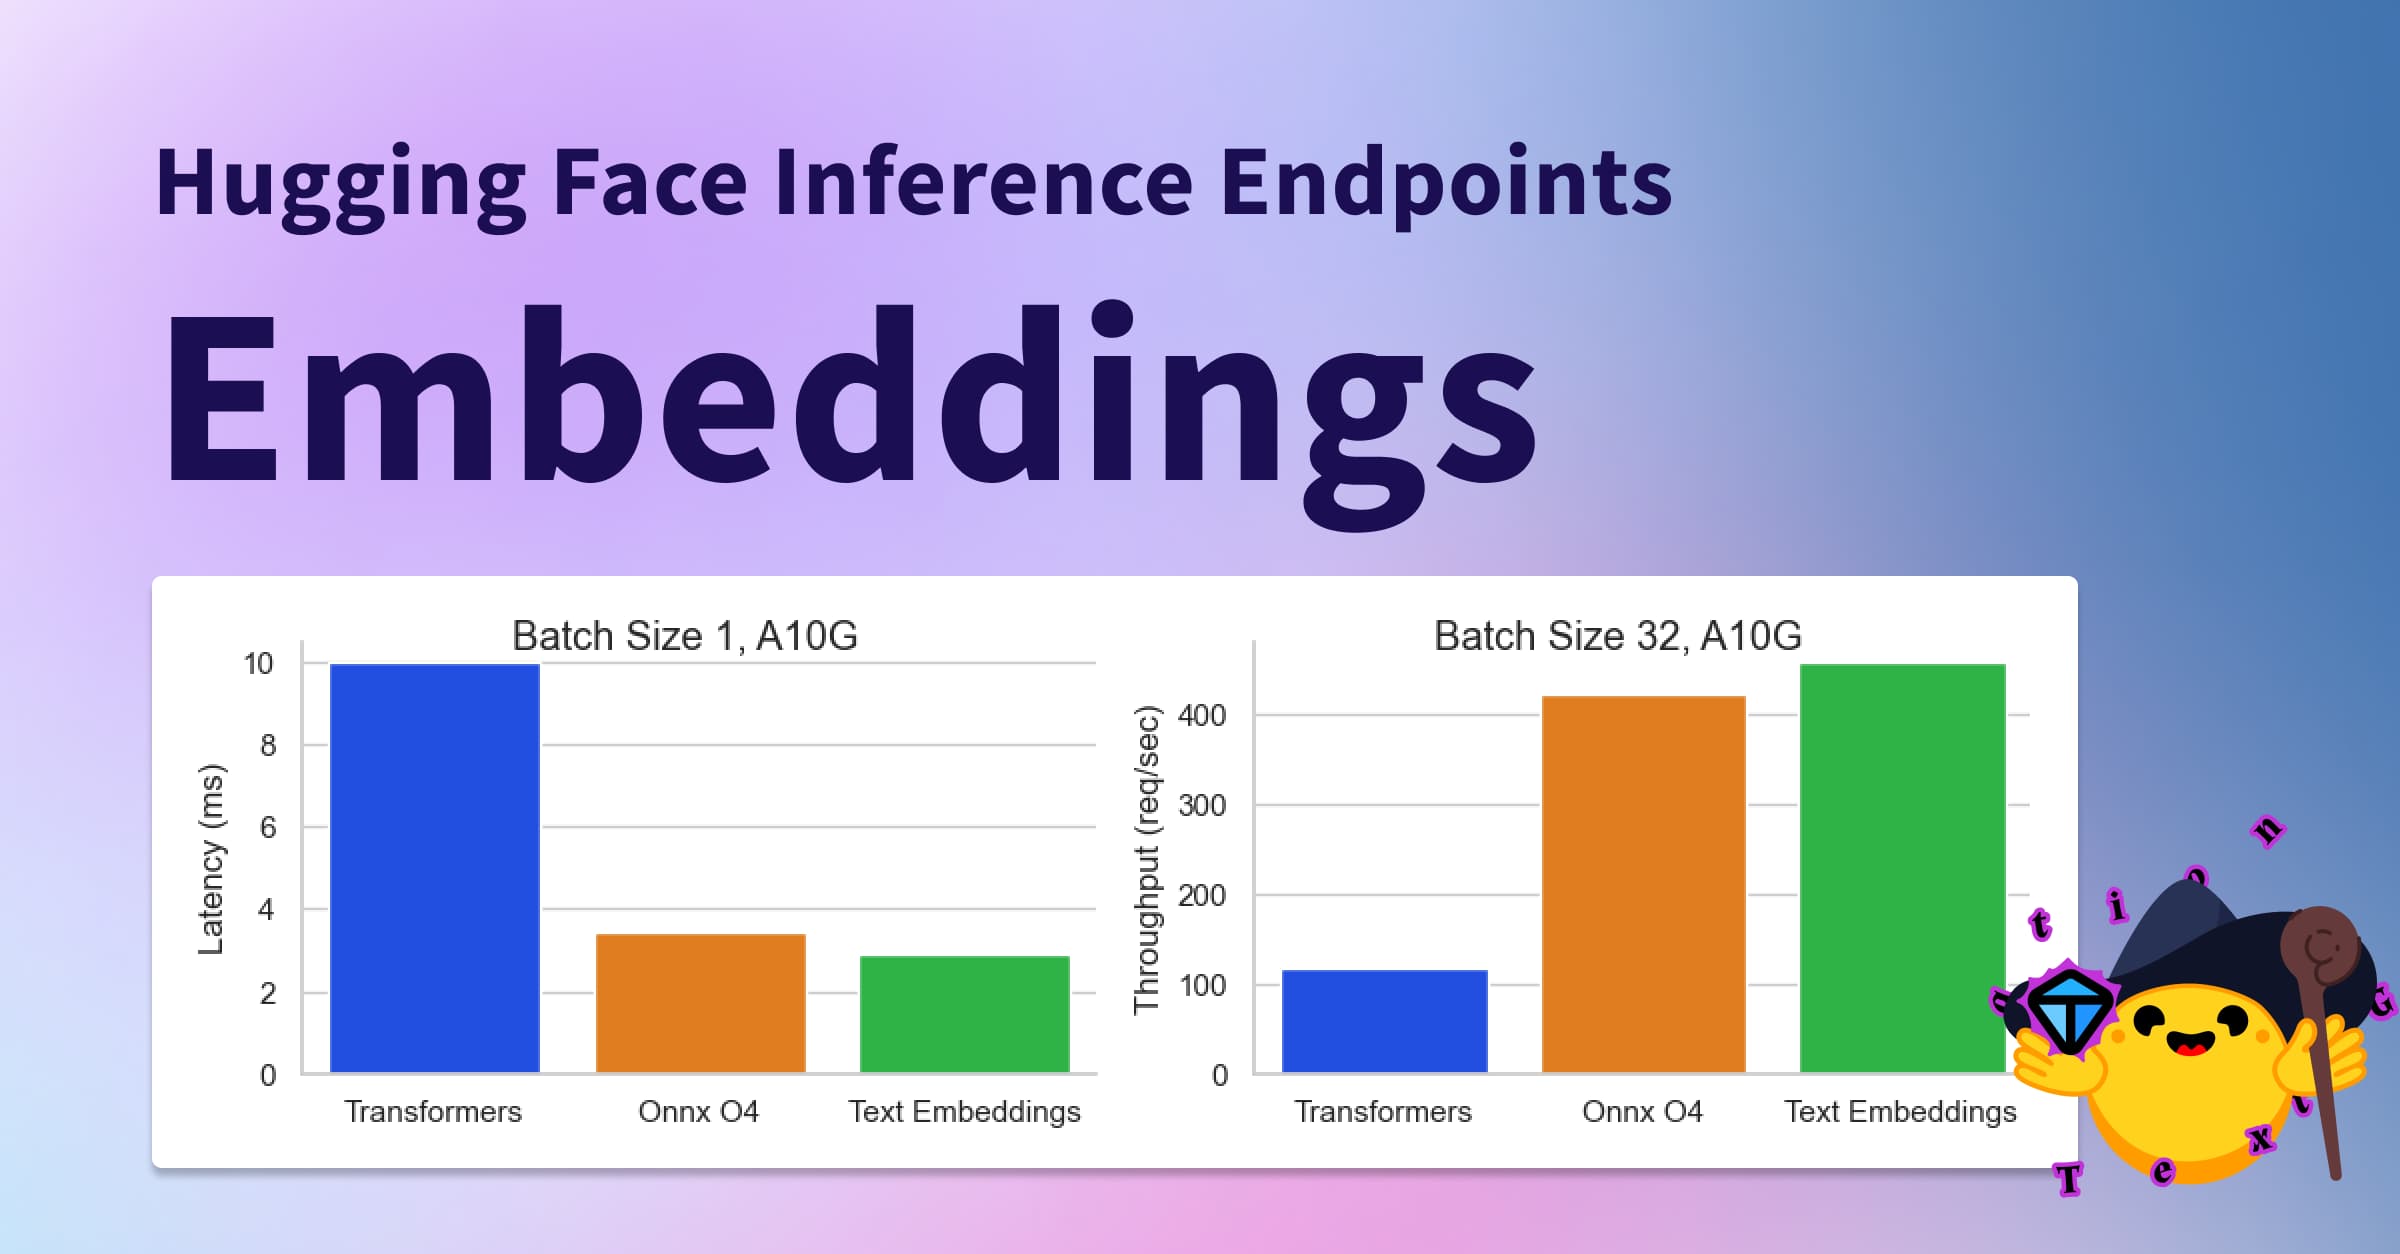
New releaseDeploy Embedding Models with Hugging Face Inference EndpointsHugging Face Blog · 1 min read
New releaseAccelerating over 130,000 Hugging Face models with ONNX RuntimeHugging Face Blog · 1 min read
New release🧨 Accelerating Stable Diffusion XL Inference with JAX on Cloud TPU v5eHugging Face Blog · 1 min read
New releaseEthics and Society Newsletter #5: Hugging Face Goes To Washington and Other Summer 2023 MusingsHugging Face Blog · 1 min read
New releaseRocket Money x Hugging Face: Scaling Volatile ML Models in ProductionHugging Face Blog · 1 min read
New releaseOverview of natively supported quantization schemes in 🤗 TransformersHugging Face Blog · 1 min read
New releaseFetch Cuts ML Processing Latency by 50% Using Amazon SageMaker & Hugging FaceHugging Face Blog · 1 min read