Prepare web content for Amazon Bedrock Knowledge Bases with Crawl4AI
Crawl4AI enhances content preparation for Amazon Bedrock Knowledge Bases by streamlining web data extraction and enrichment processes.
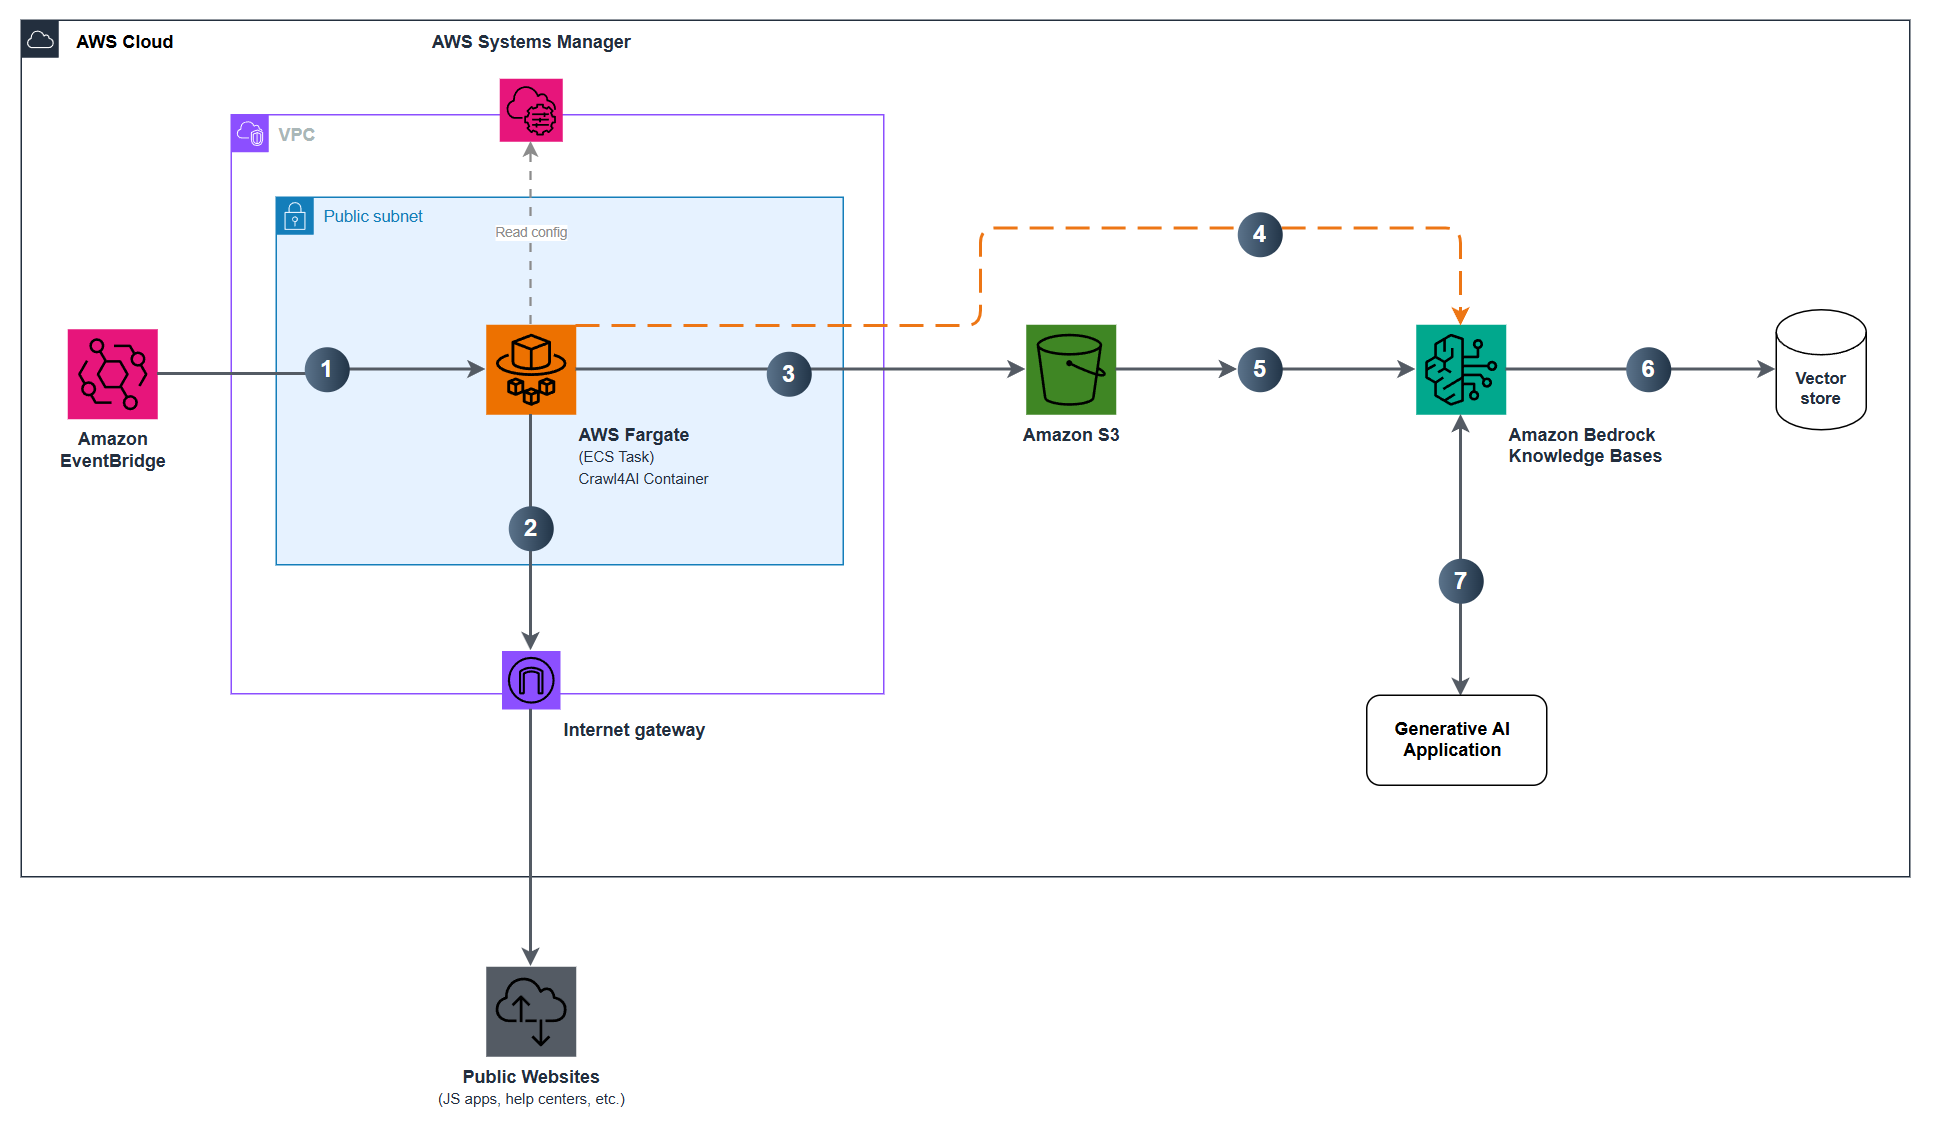
The integration of Crawl4AI with Amazon Bedrock Knowledge Bases marks a significant advancement in how organizations can prepare and manage web content. Crawl4AI, an open-source web crawler, provides a robust solution for extracting data from websites, particularly those that utilize JavaScript rendering. This capability is crucial as many modern websites rely heavily on JavaScript to display content dynamically. By using Crawl4AI, users can ensure that the data they gather is not only comprehensive but also enriched with custom metadata, making it more useful for applications that utilize Amazon Bedrock's AI capabilities.
The process begins with Crawl4AI's ability to navigate complex web structures, allowing it to selectively extract relevant information from various sources. This selective extraction is vital for organizations that need to filter out unnecessary data and focus on what truly matters for their knowledge bases. Once the content is extracted, Crawl4AI enriches it with custom metadata, which can include tags, categories, and other relevant identifiers that enhance the usability of the data once it is stored in Amazon S3. This workflow ultimately prepares the content for seamless integration into Amazon Bedrock, facilitating better AI-driven insights and applications.
Key facts
| Field | Detail |
|---|---|
| Tool | Crawl4AI |
| Function | Web crawling and content preparation |
| Target | Amazon Bedrock Knowledge Bases |
| Features | JavaScript rendering, selective extraction, metadata enrichment |
| Storage | Amazon S3 |
| Open Source | Yes |
| Release Date | Recent update in 2023 |
| Use Case | Data preparation for AI applications |
| Development | Community-driven project |
| Integration | Seamless with Amazon services |
The players involved in this development include Amazon Web Services (AWS), which is the parent company behind Amazon Bedrock, and the community of developers contributing to the Crawl4AI project. AWS is known for its extensive suite of cloud services, and Bedrock is a significant part of its machine learning offerings, allowing users to build and scale AI applications with ease. Crawl4AI, on the other hand, is an open-source initiative that thrives on community contributions and aims to provide a flexible, powerful tool for web data extraction.
Crawl4AI's introduction comes at a time when the demand for effective data preparation tools is surging. As organizations increasingly rely on AI to drive decision-making and enhance customer experiences, the need for high-quality, well-structured data has never been more critical. Previous solutions often struggled with dynamic content and required extensive manual intervention to ensure data accuracy and relevance. Crawl4AI addresses these challenges head-on, offering a streamlined approach that minimizes the need for manual data cleaning and preparation.
Historically, web crawlers have been essential in the data collection process, but many have limitations when it comes to handling JavaScript-heavy sites. Traditional crawlers often fail to render JavaScript, leading to incomplete data sets. Crawl4AI's ability to render JavaScript effectively sets it apart from its predecessors, allowing it to capture a more comprehensive view of web content. This capability is particularly important for industries such as e-commerce, news, and research, where timely and accurate data is paramount.
Who's involved
- Amazon Web Services (AWS): The cloud computing giant that provides the infrastructure for Amazon Bedrock.
- Crawl4AI Community: A group of developers and contributors who maintain and enhance the open-source web crawler.
- Data Scientists and AI Developers: Professionals who will benefit from the enriched data provided by Crawl4AI for their AI applications.
The integration of Crawl4AI with Amazon Bedrock also opens up new possibilities for businesses looking to leverage AI in their operations. By providing a reliable method for preparing web content, organizations can focus on building and deploying AI models without getting bogged down by the data preparation phase. This shift allows for faster innovation cycles and the ability to respond more quickly to market changes.
As organizations continue to adopt AI technologies, the importance of data quality cannot be overstated. High-quality data is the foundation upon which successful AI applications are built. Crawl4AI's capabilities in rendering JavaScript and enriching metadata ensure that users can access the most relevant and useful data for their needs. This focus on quality data preparation is likely to become a standard expectation in the industry, pushing other tools to evolve and improve their offerings.
How to read the numbers
While this announcement does not include specific performance metrics or benchmarks, it is essential to understand the implications of using Crawl4AI for data preparation. The effectiveness of a web crawler can often be gauged by its ability to handle complex sites, the speed of data extraction, and the accuracy of the extracted content. As Crawl4AI continues to evolve, users can expect improvements in these areas, which will further enhance its utility in preparing content for Amazon Bedrock.
What you can do with it
- Implement Crawl4AI: Start using Crawl4AI to automate the extraction of web content for your knowledge bases.
- Enhance Data Quality: Utilize the metadata enrichment features to improve the relevance and usability of your data.
- Integrate with Amazon Bedrock: Seamlessly connect your prepared content to Amazon Bedrock for AI-driven applications.
- Stay Updated: Follow the Crawl4AI community for updates and best practices in web crawling and data preparation.
What we're watching
As Crawl4AI gains traction, the next significant milestone will be the community's response to its integration with Amazon Bedrock. Developers will likely explore innovative use cases that leverage the enhanced data preparation capabilities. Additionally, any updates or improvements to Crawl4AI's performance metrics will be closely monitored, as they will directly impact its adoption and effectiveness in real-world applications.
Looking ahead, the combination of Crawl4AI and Amazon Bedrock could redefine how organizations approach data preparation for AI. With the ability to extract and enrich web content efficiently, businesses can focus more on developing AI models and less on the tedious aspects of data handling. As the landscape of AI continues to evolve, tools like Crawl4AI will play a crucial role in shaping the future of data-driven decision-making.
Source: AWS Machine Learning · Read original →
Instagram & TikTok: copy the link and paste into a Story, Reel, or caption.
Digest
AI news by email
Weekly Friday briefings plus midweek notes when models or research drop. Sources included — unsubscribe anytime.
Discussion
Comment here after signing in, or share the story to continue the conversation elsewhere.
Instagram & TikTok: copy the link and paste into a Story, Reel, or caption.
Log in or create an account to comment — Google / GitHub / X when those providers are configured.
No comments yet — start the thread.