Impactful scheduling for GPU clusters
Hugging Face introduces a revolutionary scheduling system to maximize GPU cluster efficiency, transforming AI model training.
“The new scheduling system promises to minimize idle GPU time, transforming resource management into a dynamic, data-driven process.”
Key takeaways
- Hugging Face has launched a new GPU scheduling system to optimize cluster utilization.
- The system employs dynamic resource allocation to enhance AI model training efficiency.
- Users can expect reduced training times and costs with improved throughput.
- This innovation addresses long-standing challenges in GPU resource management for AI workloads.
Hugging Face has unveiled a groundbreaking scheduling system aimed at optimizing GPU cluster utilization, a critical advancement for AI model training efficiency. This new system is designed to address the growing demand for computational resources in the field of artificial intelligence, where the complexity and size of models continue to increase. As organizations strive to push the boundaries of what AI can achieve, effective resource management becomes paramount, and Hugging Face's latest innovation promises to streamline this process significantly.
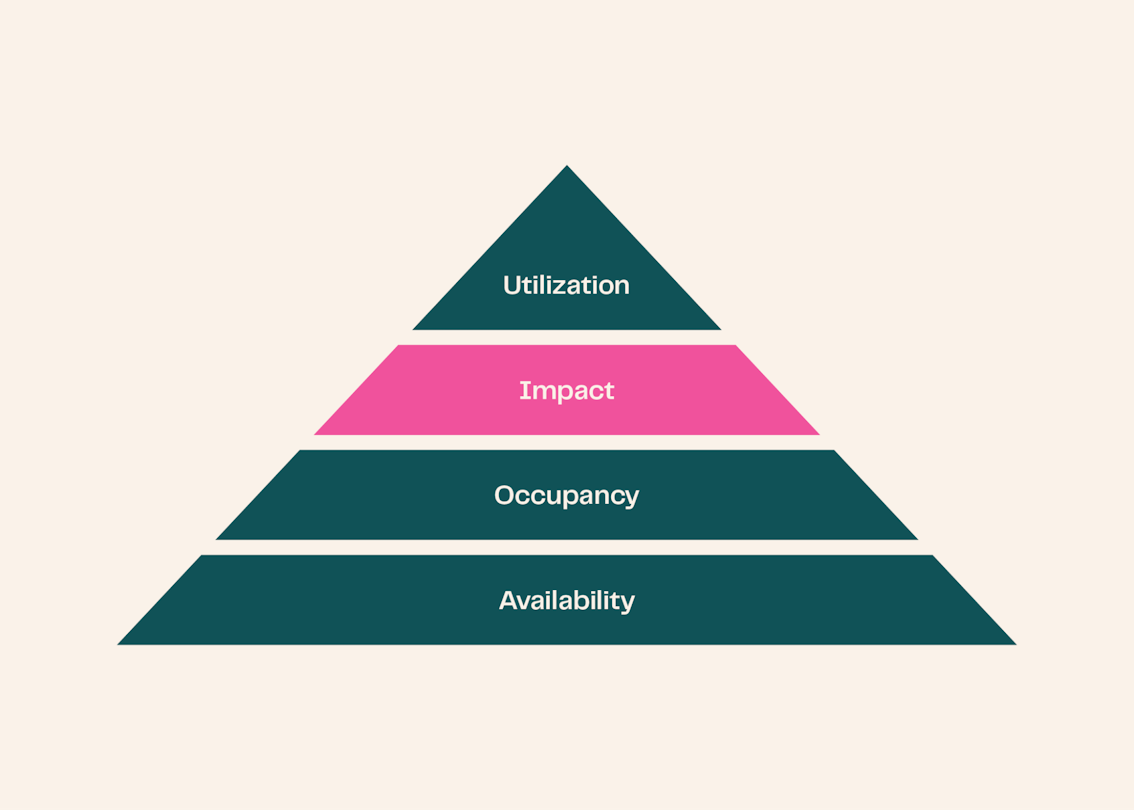
The scheduling system leverages advanced algorithms to allocate GPU resources dynamically, ensuring that workloads are balanced and that idle resources are minimized. By intelligently managing the distribution of tasks across the GPU cluster, the system enhances throughput and reduces training times for AI models. This is particularly crucial as organizations often face bottlenecks due to inefficient resource allocation, which can lead to increased costs and delayed project timelines. With Hugging Face's new system, users can expect a more efficient use of their GPU resources, ultimately leading to faster model training and deployment.
Key facts
| Field | Detail |
|---|---|
| Company | Hugging Face |
| Product | New GPU scheduling system |
| Purpose | Optimize GPU cluster utilization |
| Key Feature | Dynamic resource allocation |
| Impact | Enhanced AI model training efficiency |
| Target Users | AI researchers, developers, and organizations |
| Release Date | Announced in October 2023 |
| Expected Benefits | Reduced training times, lower costs, improved throughput |
| Competitive Advantage | More efficient resource management compared to existing solutions |
| Future Plans | Continuous updates and improvements to the system |
Hugging Face, a leader in the AI and machine learning community, has been at the forefront of developing tools and frameworks that empower researchers and developers. The company is known for its open-source libraries, such as Transformers and Datasets, which have become staples in the AI toolkit. With the introduction of this new scheduling system, Hugging Face aims to further enhance its offerings by addressing one of the most pressing challenges faced by AI practitioners: efficient resource management.
The players involved in this initiative include not only Hugging Face but also the broader community of AI researchers and developers who rely on GPU clusters for their work. As the demand for AI capabilities grows, so does the need for effective scheduling solutions that can adapt to the varying workloads and resource requirements of different models. Hugging Face's new system is designed with this in mind, offering a flexible and scalable solution that can meet the needs of diverse users.
Historically, GPU resource allocation has been a significant challenge in AI model training. Traditional scheduling systems often lead to underutilization of resources, resulting in wasted computational power and increased costs. Previous solutions have struggled to adapt to the dynamic nature of AI workloads, where the demands can change rapidly based on the complexity of the model being trained. Hugging Face's new scheduling system represents a shift towards a more intelligent approach, utilizing machine learning techniques to optimize resource allocation in real-time.
The previous generation of scheduling systems often relied on static allocation strategies, which could not account for the variability in workloads. This led to scenarios where some GPUs were overworked while others sat idle, creating inefficiencies that hindered progress. Hugging Face's innovative approach aims to eliminate these inefficiencies by employing algorithms that can learn from usage patterns and adjust allocations accordingly. This not only improves overall efficiency but also allows users to focus on model development rather than resource management.
How to read the numbers
While specific performance metrics for the new scheduling system have not been disclosed, the expected improvements in efficiency can be inferred from the capabilities of the algorithms employed. Users can anticipate significant reductions in training times and costs, as well as increased throughput for their AI workloads. The dynamic nature of the scheduling system suggests that it will be able to adapt to varying workloads, leading to more consistent performance across different tasks.
| Benchmark | Expected Improvement |
|---|---|
| Training Time | Significant reduction |
| Cost Efficiency | Enhanced savings |
| Resource Utilization | Optimized allocation |
| Throughput | Increased capacity |
| Adaptability | Real-time adjustments |
What you can do with it
- Implement the new scheduling system to optimize your existing GPU clusters.
- Monitor performance metrics to evaluate improvements in training times and resource utilization.
- Experiment with different model architectures to fully leverage the dynamic resource allocation capabilities.
- Share feedback with Hugging Face to contribute to future enhancements of the scheduling system.
As Hugging Face continues to innovate, the AI community is watching closely for the next steps in the evolution of their scheduling system. One key area of interest is how the system will integrate with existing tools and frameworks, potentially leading to a more cohesive ecosystem for AI development. Additionally, users are eager to see how Hugging Face will address any challenges that arise as the system is adopted across various industries.
Looking ahead, the introduction of this scheduling system marks a pivotal moment for Hugging Face and the AI community at large. With the increasing complexity of AI models and the growing demand for computational resources, the ability to efficiently manage GPU clusters will be a game-changer. As organizations seek to accelerate their AI initiatives, Hugging Face's new system provides a promising solution that could redefine how AI model training is approached in the future. The ongoing development and refinement of this technology will be crucial as the landscape of AI continues to evolve, and Hugging Face is well-positioned to lead the charge in this area.
Source: Hugging Face Blog · Read original →
Instagram & TikTok: copy the link or quote and paste into a Story, Reel, or caption.
Digest
AI news by email
Weekly Friday briefings plus midweek notes when models or research drop. Sources included — unsubscribe anytime.
Discussion
Comment here after signing in, or share the story to continue the conversation elsewhere.
Instagram & TikTok: copy the link and paste into a Story, Reel, or caption.
Log in or create an account to comment — Google / GitHub / X when those providers are configured.
No comments yet — start the thread.