Fit More and Train Faster With ZeRO via DeepSpeed and FairScale
DeepSpeed and FairScale leverage ZeRO technology to enhance model training efficiency, enabling faster and more memory-efficient processes.
DeepSpeed and FairScale have announced a significant enhancement to their training frameworks with the integration of ZeRO technology, aimed at improving the efficiency of training large-scale AI models. This development allows developers to train models with billions of parameters while significantly reducing GPU memory usage. By optimizing memory efficiency, the new capabilities promise to accelerate the training process, making it more feasible for organizations to work with larger models without incurring prohibitive costs associated with hardware resources.
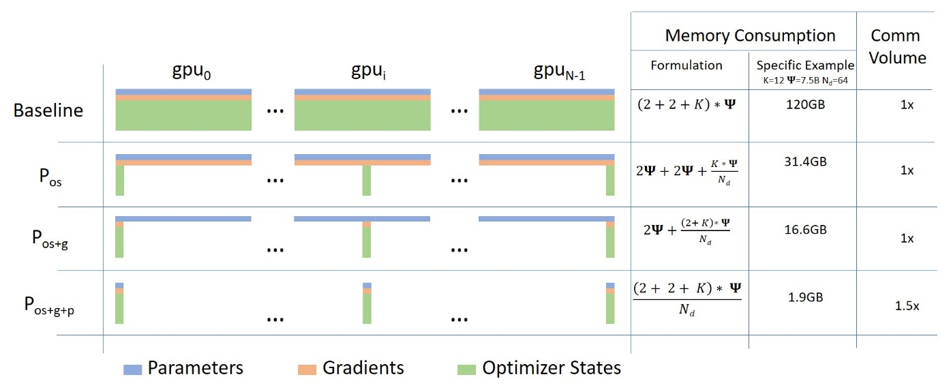
The ZeRO (Zero Redundancy Optimizer) technology, originally developed by Microsoft, focuses on optimizing memory usage during the training of deep learning models. By partitioning the model states across multiple GPUs, ZeRO minimizes the memory footprint required for each individual GPU. This means that developers can leverage existing hardware more effectively, allowing for the training of larger models that were previously constrained by memory limitations. The integration with both DeepSpeed and FairScale ensures that developers using PyTorch can easily adopt these enhancements into their existing workflows, streamlining the process of building and training complex models.
Key facts
| Field | Detail |
|---|---|
| Technology | ZeRO technology from Microsoft |
| Frameworks | DeepSpeed and FairScale |
| Compatibility | PyTorch |
| Key Benefit | Improved memory efficiency and reduced GPU usage |
| Target Users | Developers working with large-scale AI models |
| Model Capacity | Supports training of models with billions of parameters |
The broader implications of this advancement are significant for the AI and machine learning community. As organizations increasingly seek to develop more sophisticated models, the demand for efficient training solutions has never been higher. Previous iterations of model training often faced bottlenecks due to memory constraints, which limited the size and complexity of models that could be feasibly trained. With ZeRO's introduction into DeepSpeed and FairScale, developers now have access to tools that can help overcome these challenges, potentially leading to breakthroughs in various applications ranging from natural language processing to computer vision.
Looking ahead, the integration of ZeRO technology into popular frameworks like DeepSpeed and FairScale is likely to set a new standard for model training efficiency. As more developers adopt these tools, we can expect to see an increase in the scale and complexity of AI models being developed. This shift not only has the potential to drive innovation in AI applications but also raises questions about the future of hardware requirements and the cost structures associated with training large models. With the landscape of AI development continually evolving, the focus will now be on how effectively these new capabilities can be utilized and what new models will emerge as a result.
Source: Hugging Face Blog · Read original →
Discussion
Comment here after signing in, or share the story to continue the conversation elsewhere.
Instagram & TikTok: copy the link and paste into a Story, Reel, or post caption.
Log in or create an account to comment — Google / GitHub / X when those providers are configured.
No comments yet — start the thread.



