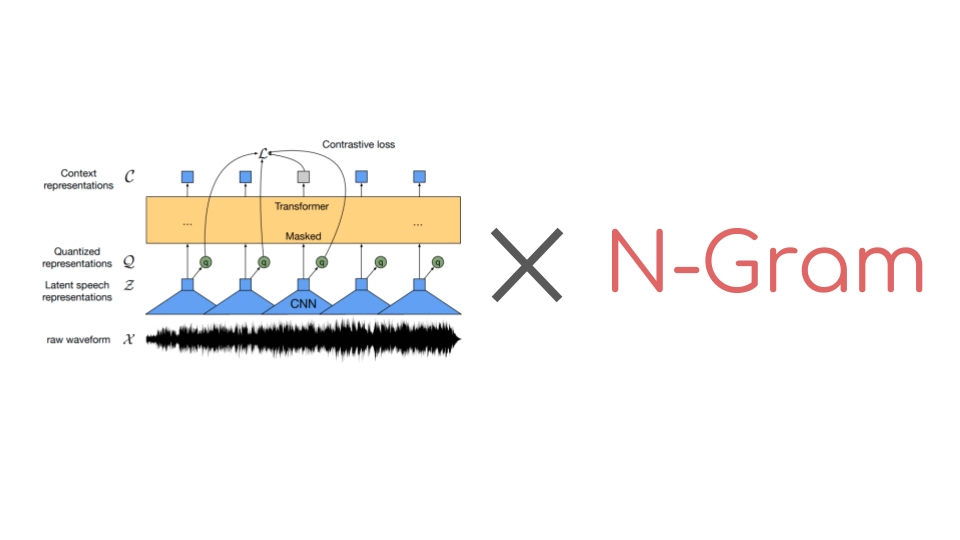
Boosting Wav2Vec2 with n-grams in 🤗 Transformers
Hugging Face enhances Wav2Vec2 with n-grams, boosting speech recognition accuracy for developers and researchers.
Hugging Face has announced a significant upgrade to its popular Wav2Vec2 model by integrating n-grams into the latest version of the Transformers library. This enhancement aims to improve the model's performance in speech recognition tasks, a domain where accuracy is paramount. With n-grams, the model can better capture contextual information from audio inputs, leading to more precise transcriptions and a better understanding of spoken language nuances. This upgrade is now available for users who can access the latest version of the Hugging Face Transformers library, making it easier for developers to implement these improvements in their applications.
The integration of n-grams into Wav2Vec2 represents a notable advancement in the field of automatic speech recognition (ASR). N-grams are sequences of 'n' items from a given sample of text or speech, and their use in language models has been well-established. By incorporating this technique, Hugging Face aims to leverage the contextual relationships between words in speech, thereby enhancing the model's ability to predict and transcribe spoken language more accurately. This is particularly beneficial in environments where clarity and precision are critical, such as in transcription services, voice assistants, and accessibility tools.
Key facts
| Field | Detail |
|---|---|
| Model | Wav2Vec2 |
| Upgrade | Integration of n-grams |
| Library | Hugging Face Transformers |
| Application | Speech recognition tasks |
| Expected Outcome | Enhanced accuracy in transcriptions |
| Availability | Latest version of the Hugging Face Transformers |
The introduction of n-grams into Wav2Vec2 is a response to the growing demand for more sophisticated speech recognition systems. As the technology landscape evolves, the need for accurate transcription and understanding of spoken language has become increasingly important. This upgrade not only enhances the capabilities of Wav2Vec2 but also aligns with broader trends in machine learning where context-aware models are becoming the standard. Similar advancements have been seen in other models, such as OpenAI's Whisper, which also focuses on improving transcription accuracy through advanced techniques.
Looking ahead, the implications of this upgrade are substantial for both developers and researchers. As they begin to implement the new features, they will likely discover new applications and use cases for Wav2Vec2 that were previously unattainable due to accuracy limitations. The community's feedback on this upgrade will be crucial in shaping future iterations of the model, and it will be interesting to see how Hugging Face continues to innovate in the realm of speech recognition technology. With ongoing advancements, users can expect even more powerful tools that push the boundaries of what is possible in natural language processing.
Source: Hugging Face Blog · Read original →
Discussion
Comment here after signing in, or share the story to continue the conversation elsewhere.
Instagram & TikTok: copy the link and paste into a Story, Reel, or post caption.
Log in or create an account to comment — Google / GitHub / X when those providers are configured.
No comments yet — start the thread.



